
Picking a model
By Daniel Samson · 2026-10-28
I have been experimenting with running large language models locally instead of using the cloud models, such as Claude or GPT. The influencers online, do not show a real software engineering workflows. I don’t want to know which model is best at making a short story. I want to replace Claude code with my local model. Every YouTuber I see, has a consumer mindset.
Right model for the job
After testing many different models, the only one that practically matters for coding and terminal usage is Qwen 3.8 27b. Running a GPU with less than 120GB of RAM, it is the model that performs the best on the benchmarks. If you are serious about running your own models, you need at least 32GB of dedicated graphics memory, in order to run this model with the full 256k token context window. If you are rich enough to afford hundreds of thousands of dollars for a real HPC GPU server, then you can run the real open frontier models with trillions of parameters. Those with 128-512 GB, the flash next variations is the choice. For the rest of us, it’s 27b.
Real work vs Benchmarks
Let’s be honest. The benchmarks you will find online will never truly compare to your actual workflow. The local models you can run will never keep up with the data centres which are purpose built. So don’t expect to have the latest version of a frontier model running at 1000 tokens per second. I have been using artificial analysis as a rough idea.
Intelligence
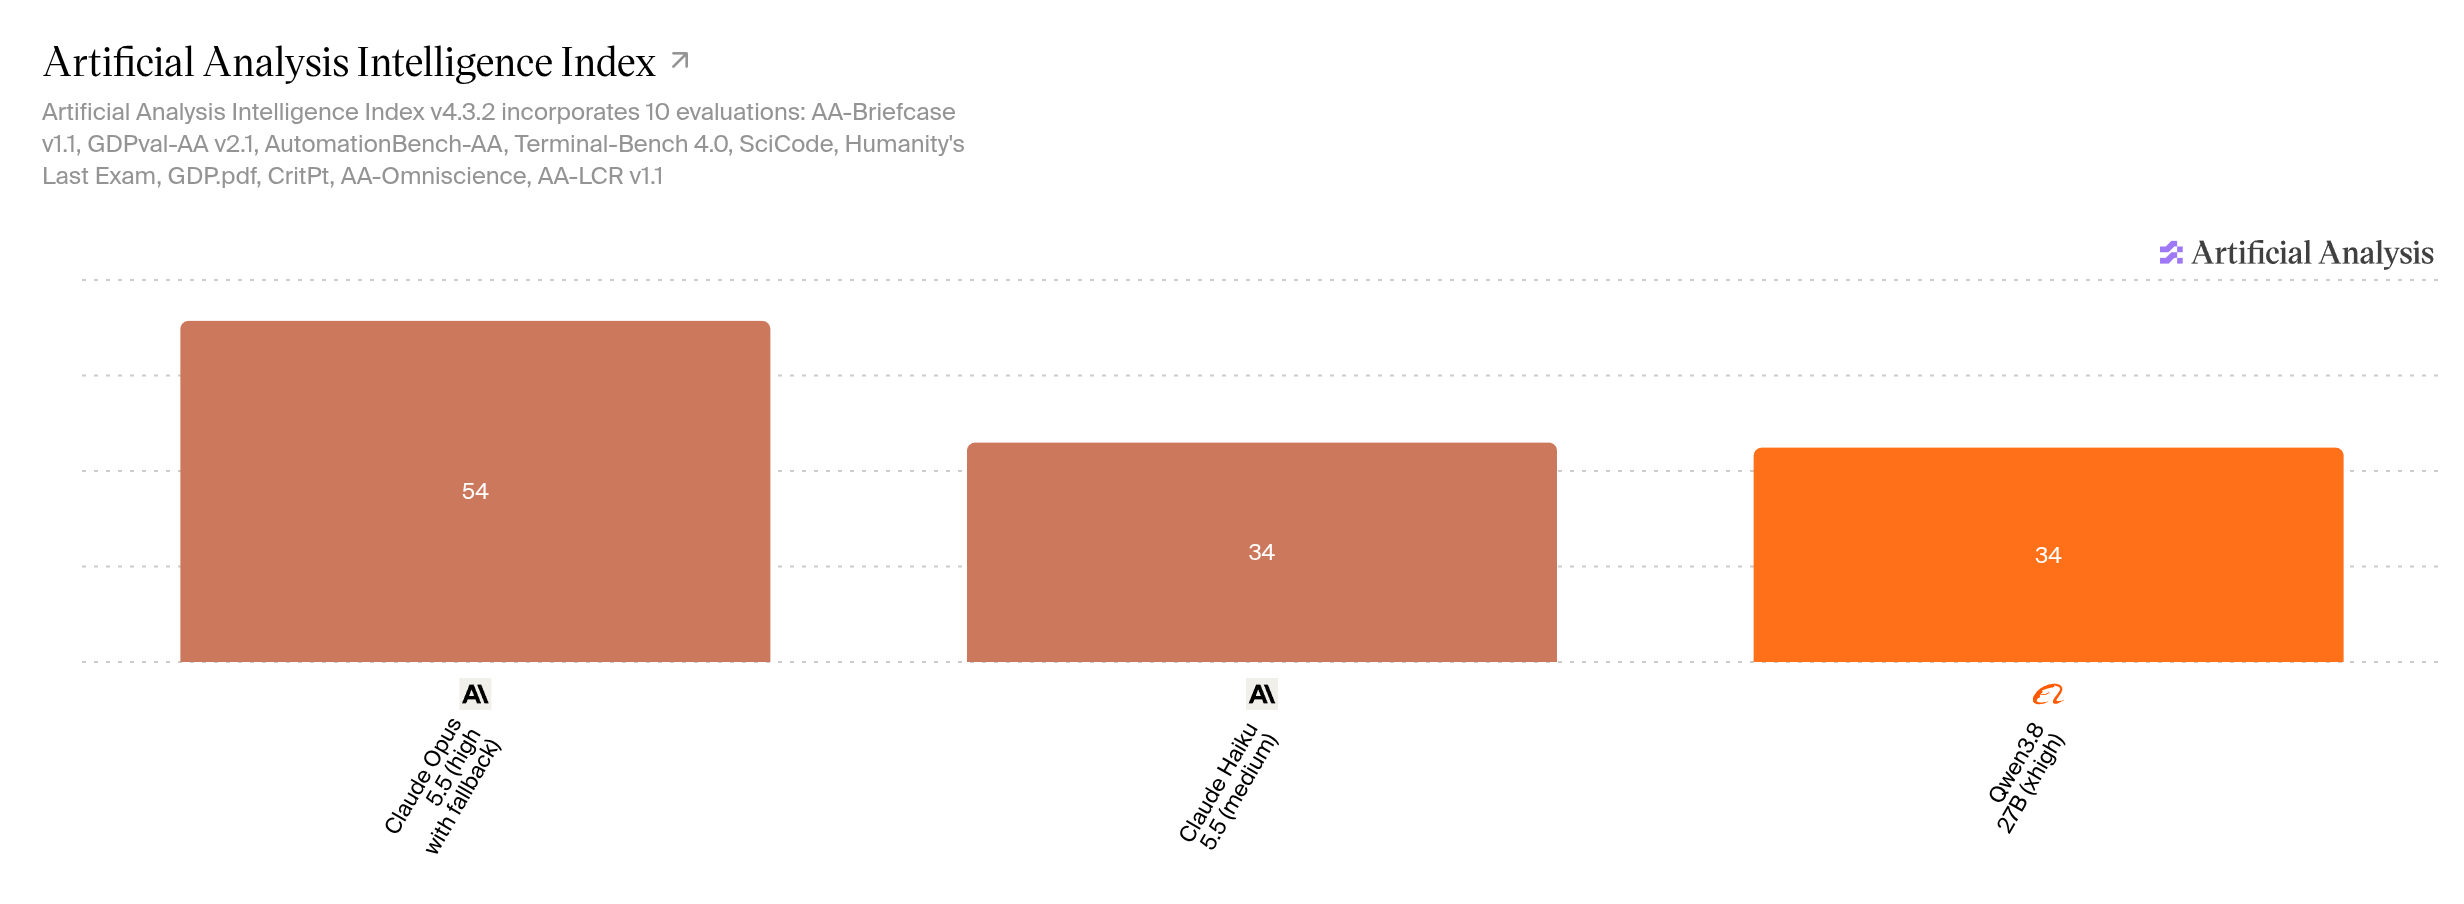
It not good enough to have a model that just maximises coding, it also needs to be able to make the right decisions.
Coding Benchmarks
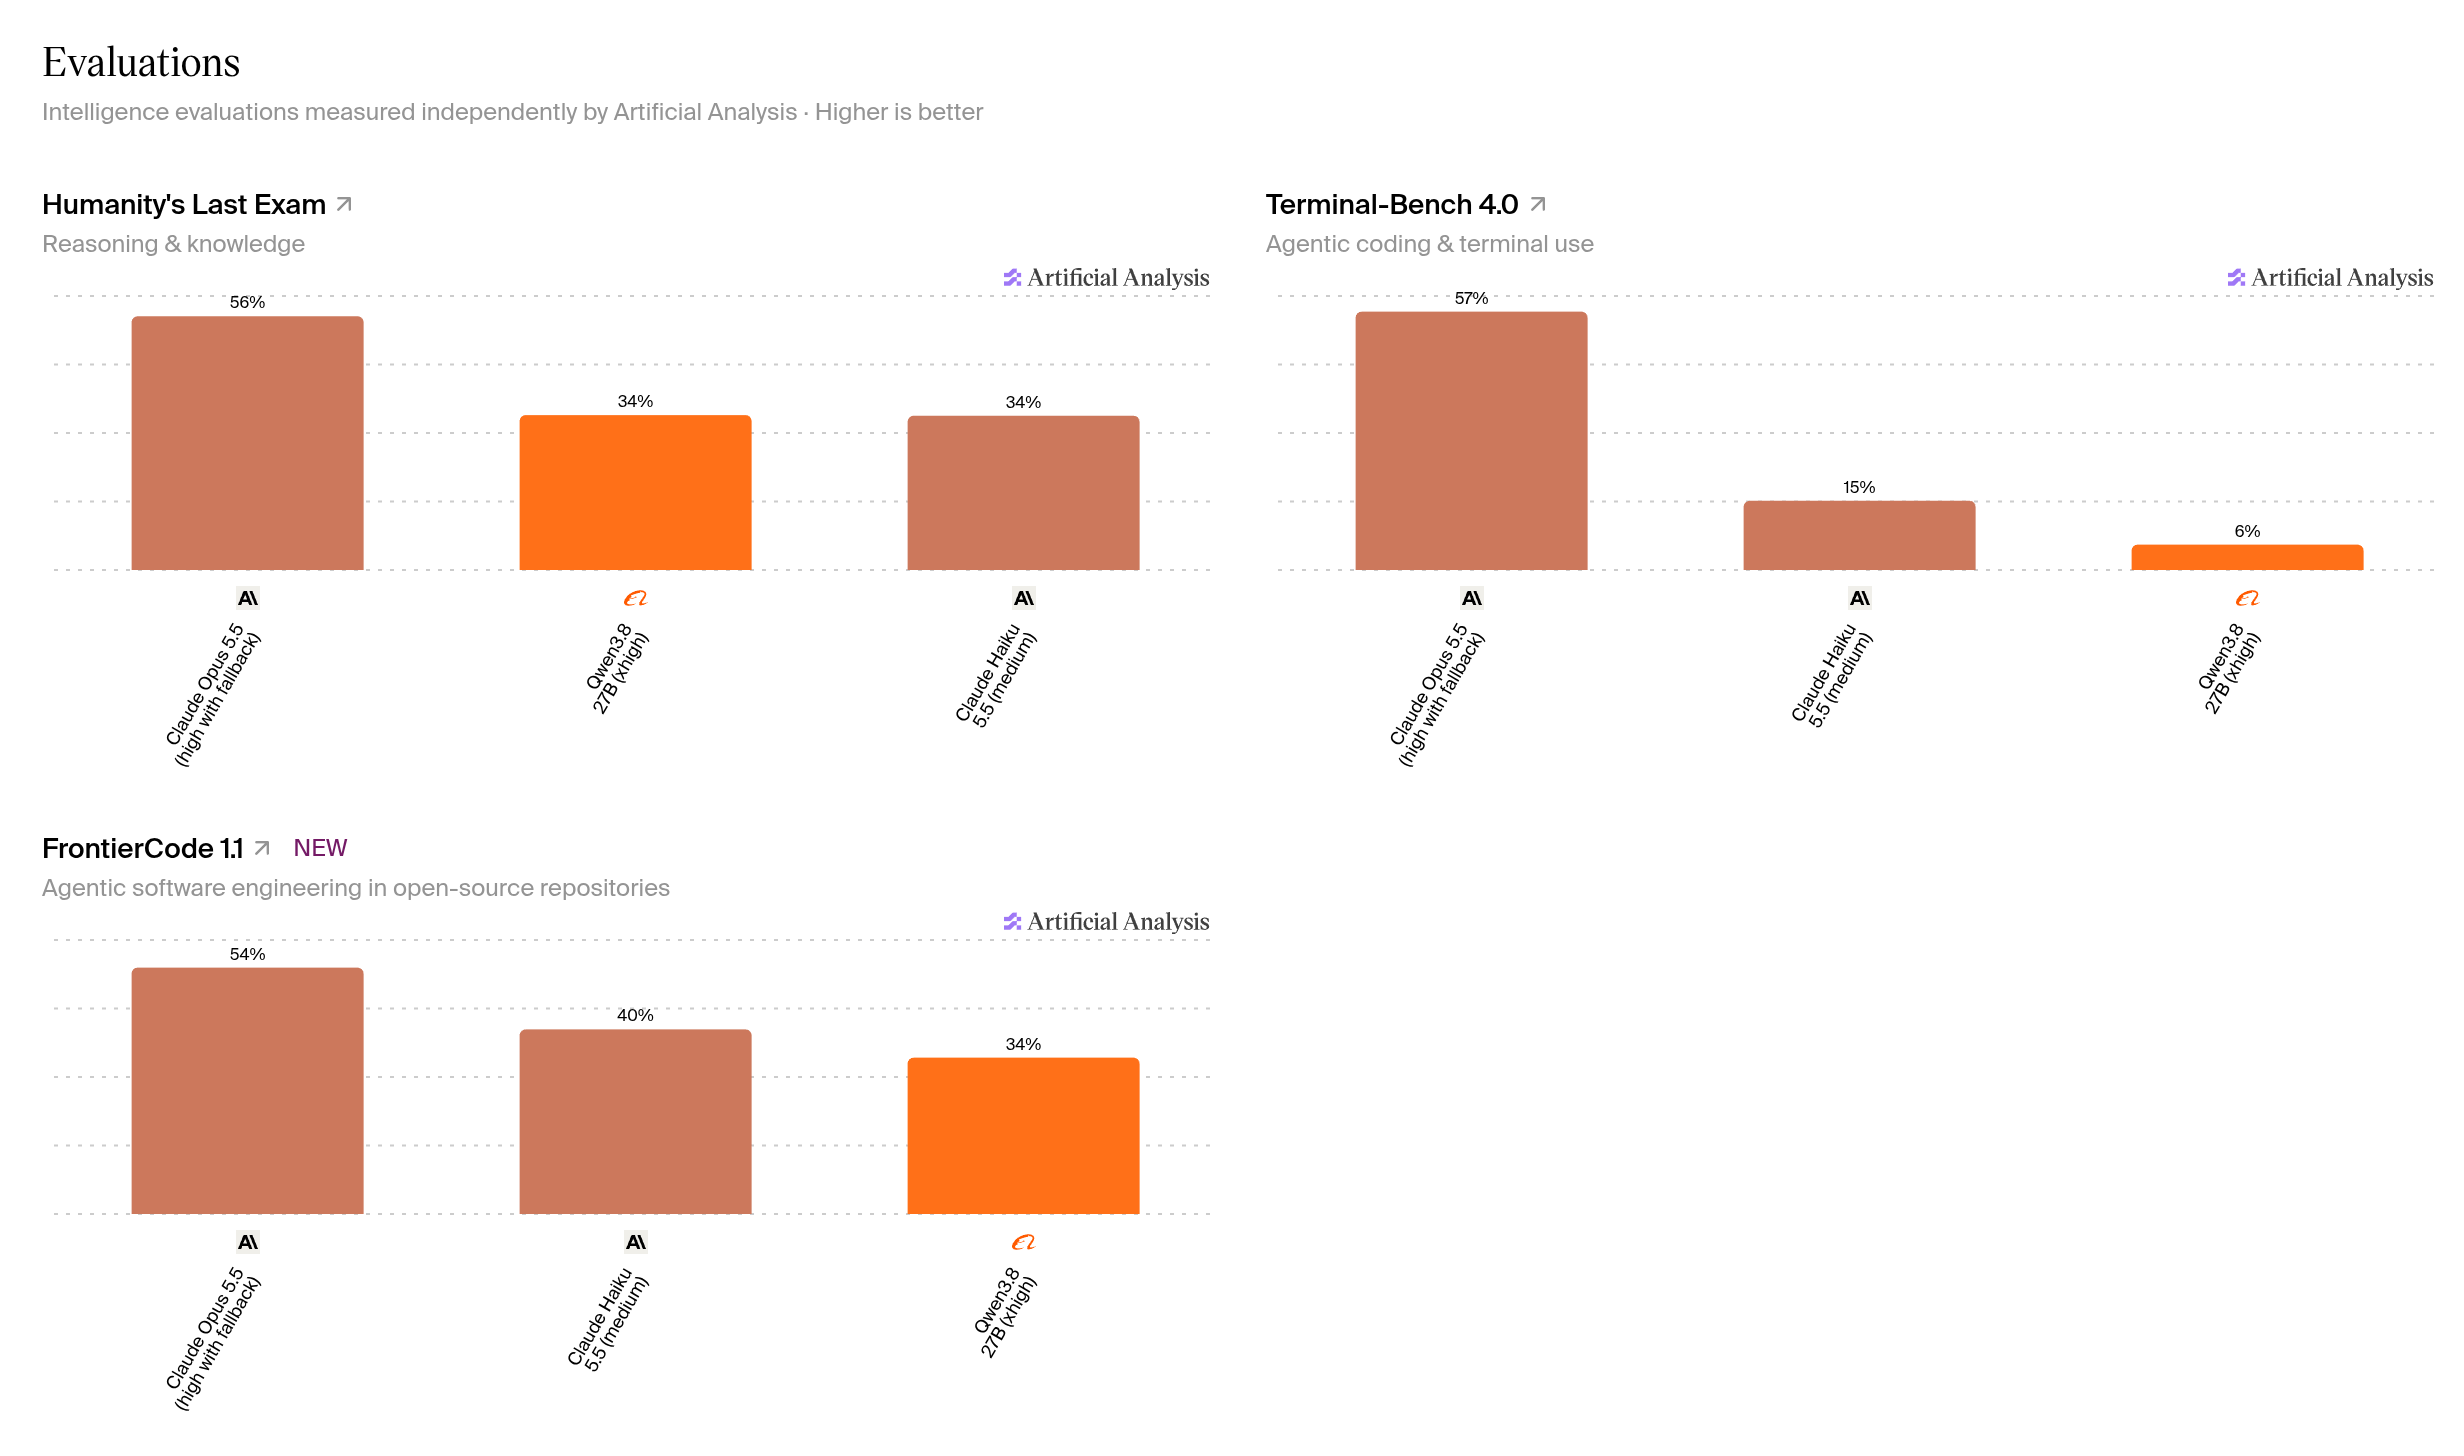
Coding benchmarks are a good starting place. They primarily use python though. So if you typically work in an other language and framework; you need to take them with a pinch of salt.
Speed Matters
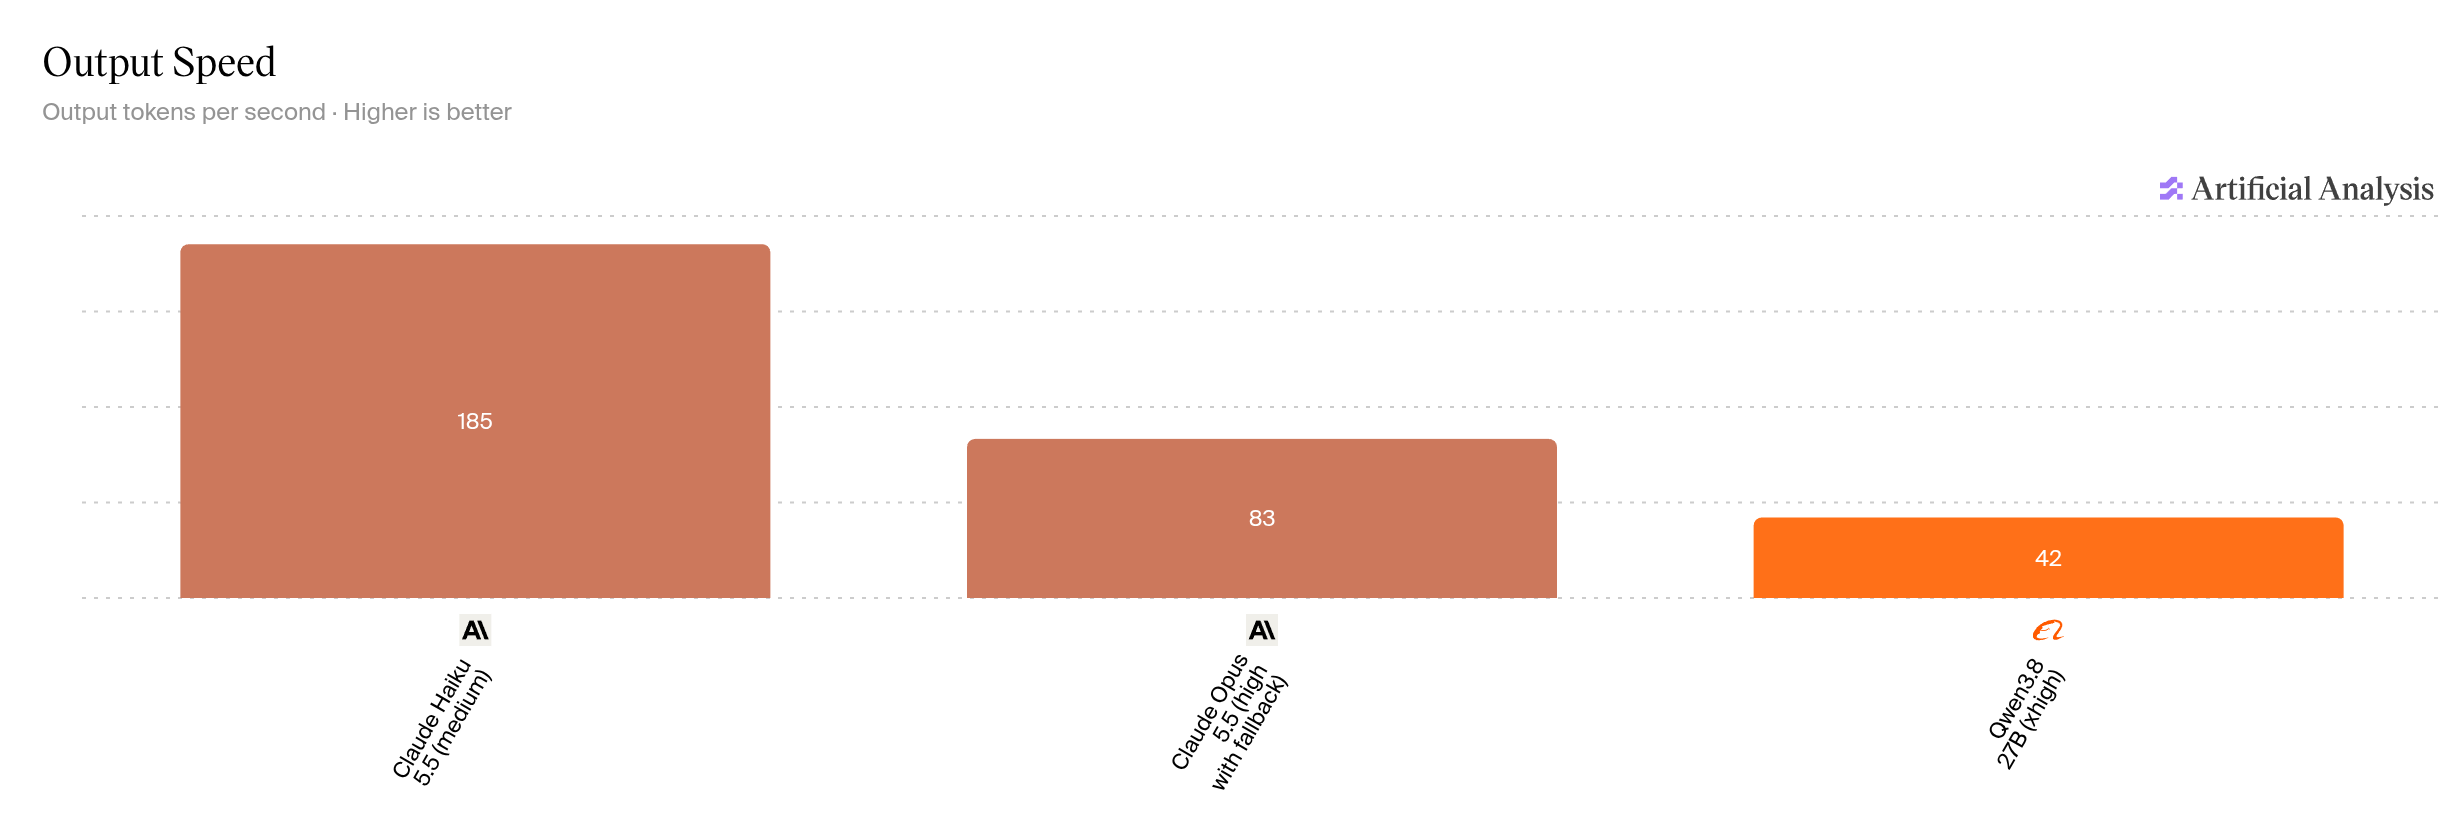
In my tests, the cloud models always complete the prompts correctly and in less time. Which is fine if you don’t mind waiting a little longer for a local model.
Only use what you need
In my real job, I have discovered that I don’t actually need to run the biggest models. I have been using smaller models to work on 5 million lines of code. Qwen 27b has the capability of a Claude Opus 4.5. Which is what Claude was like in around November 2025. Yes, you have to give it a bit more information than the latest frontier models, though are not paying £200 per month for the pleasure.
Conclusion
So be realistic, and sign up for the API to run the harder tasks, that need to completed immediately.